AI in Trading
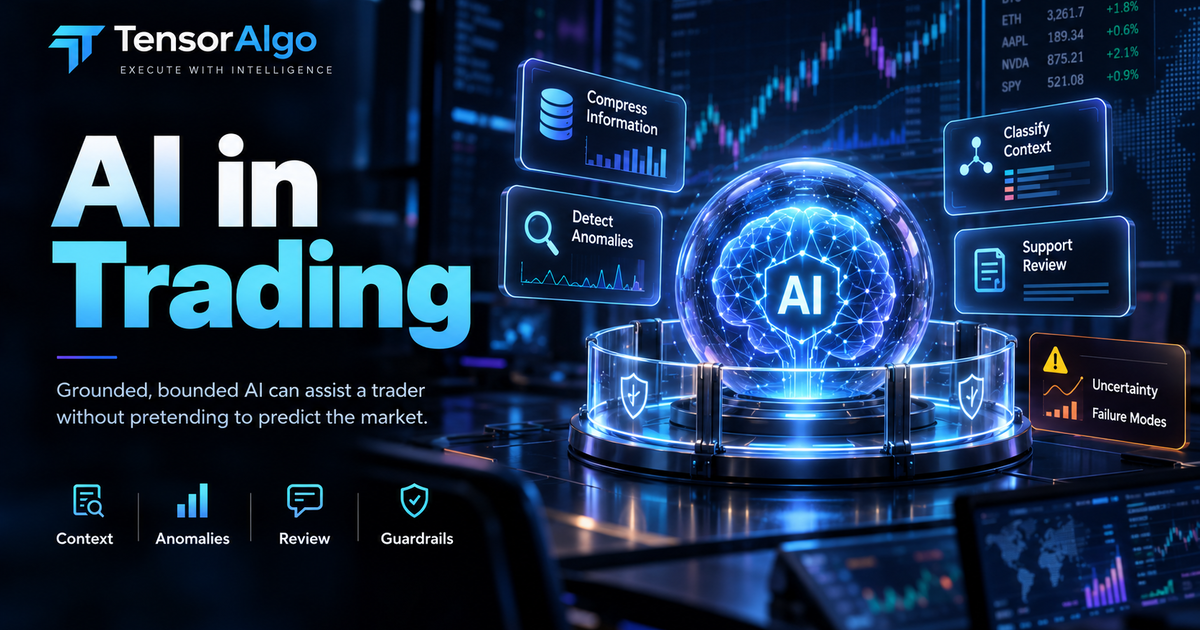
AI can compress information, classify context, detect anomalies and support review - but it also introduces uncertainty and new failure modes. This guide shows how grounded, bounded AI can support a trader without pretending to predict the market.
AI in Trading: What It Can Do, What It Cannot, and How to Use It Responsibly
“AI in trading” covers very different technologies: statistical machine learning, anomaly detection, classification, natural-language models, computer vision, and rule systems enhanced by learned models. Treating all of them as one predictive machine creates unrealistic expectations.
Educational information only. AI output is uncertain; futures are leveraged and involve substantial risk.
Four practical roles for AI
1. Information compression
AI can summarize market context, news or internal analytics and reduce the time required to inspect many inputs.
2. Classification
Models can classify regimes, setups, historical examples, or operational states when labels and features are well defined.
3. Pattern and anomaly detection
Machine learning can surface relationships or unusual observations that are difficult to encode manually.
4. Workflow assistance
Language models can help document playbooks, review journals, explain analytics, and translate structured data into readable analysis.
None of these roles implies certainty about the next price move.
LLMs are not price oracles
Large language models are designed to model and generate language. They can reason over supplied market data, but they can also hallucinate, misread stale context, or sound confident when evidence is weak.
A production workflow should ground an LLM in authoritative data, expose timestamps/source quality, constrain outputs, and validate actions separately.
Machine learning depends on labels
A model learns the objective encoded by its target. If “good trade” is labeled poorly, the model can optimize the wrong behavior.
Define:
- prediction horizon;
- target/outcome;
- decision timestamp;
- available features;
- treatment of costs;
- train/validation/test boundaries.
The label is part of the strategy.
Data leakage can make AI look brilliant
Leakage occurs when training or evaluation receives information unavailable at decision time. Time-series data requires chronological validation. Normalization, feature engineering, revised data, and target construction can all leak future information.
High historical accuracy with leakage is not an edge.
Nonstationarity is the central challenge
Markets change. Relationships learned in one volatility, liquidity, or macro regime may weaken in another.
Monitor feature distributions, calibration, performance by regime, and the age of training data. Retraining is not automatically the answer: a newly trained model can also be worse.
Confidence needs calibration
A model output of 0.8 should not casually be interpreted as “80% chance this trade wins.” Scores can be rankings, logits, similarities, or uncalibrated probabilities.
If probability language is used, validate calibration on unseen data and clearly define the event being predicted.
Human-in-the-loop versus autonomous execution
AI assistance can range from research-only to fully automated. The higher the autonomy, the stronger the controls required:
- strict order/risk limits;
- data freshness guards;
- idempotency;
- position reconciliation;
- audit logs;
- model/version tracking;
- fallback behavior;
- kill switches.
A language model should not be the only risk control.
Evaluate the whole decision system
Do not evaluate only model accuracy. Measure whether the AI changes decisions in a useful way after costs and risk.
Possible metrics include precision/recall for setup filtering, calibration, false-positive cost, incremental expectancy, drawdown effects, latency, abstention quality, and human override outcomes.
Shadow mode before live influence
A new model can run alongside the existing process without changing decisions. This creates forward evidence under real conditions. Promotion from shadow to live influence should have explicit criteria and rollback rules.
Shadow mode is useful only if its outcomes are actually measured.
Where generative AI fits
Generative AI is particularly useful for:
- explaining complex analytics;
- synthesizing structured evidence;
- retrieving relevant historical examples;
- journal review;
- hypothesis generation;
- converting natural-language playbooks into candidate rules.
Hypotheses still require testing.
How TensorAlgo Fits
TensorAlgo combines structured market analytics with AI-assisted workflows while keeping user-defined Playbooks and underlying evidence visible. The practical boundary is important: AI can help organize, explain and review evidence, while deterministic calculations, permissions and risk controls should remain independently verifiable. See the Support Center for current functionality.
AI Is an Umbrella Term
Separate deterministic rules, classical statistical models, machine learning, deep learning and generative AI. They solve different problems. A language model that summarizes market context should not be evaluated with the same metric as a classifier estimating a regime label or a deterministic engine enforcing a maximum quantity.
Prediction Is Only One Use Case
Some of the highest-value applications do not predict price at all: extracting structured fields, retrieving similar historical cases, detecting data anomalies, summarizing journals, explaining model outputs and monitoring operational state. These tasks can improve workflow quality without claiming directional foresight.
A Grounded AI Architecture
A robust assistant can use authoritative data → retrieval/tools → constrained model → deterministic validation → user/action layer. Give every market input a timestamp and provenance. If required data is stale, the correct output may be abstention rather than an invented analysis.
Hallucination and Tool Errors
Generative models can fabricate facts, misread tool output or preserve an obsolete assumption. Production systems should validate symbols, timestamps, numerical ranges and permissions outside the model. Tool calls should be idempotent where actions can be retried, and consequential actions should have explicit authorization boundaries.
Evaluating an AI Filter
If AI filters trading opportunities, evaluate accepted and rejected cases. Suppose it removes 30 losing trades but also removes 25 larger winners: headline “loss avoidance” is misleading. Measure incremental expectancy, precision/recall for the target event, drawdown effects, abstention rate and performance by regime.
Shadow Mode and Promotion
A candidate model can run on live-arriving data without changing production decisions. That produces forward evidence. Promotion should require predefined evidence, baseline comparison, versioning and rollback. Forward Testing explains why a learning system without a promotion path remains research rather than live adaptation.
Model Risk
AI introduces model risk in addition to market risk: training-data bias, leakage, drift, calibration failure, dependency outages and prompt/tool regressions. The NIST AI Risk Management Framework provides a general framework for governing AI risk, while financial-market implementation still requires domain-specific controls.
AI and Financial Claims
The SEC's investor guidance on artificial intelligence is a useful reminder to treat extraordinary AI investment claims skeptically. An “AI-powered” label does not establish accuracy, profitability or suitability.
Data Provenance
Every AI conclusion should be traceable to inputs: source, symbol, timestamp, expiry where relevant and calculation version. Provenance makes it possible to distinguish a model error from stale or incorrect upstream data.
Retrieval-Augmented Analysis
Rather than asking a language model to remember product facts, retrieve current documentation, market state and playbook rules at runtime. Retrieval reduces reliance on model memory, but retrieved material still needs freshness and permission checks.
Structured Outputs
Constrain model output into fields such as regime, evidence, uncertainty, missing inputs and explanation. Validate types and ranges before displaying or acting. Structured outputs are easier to test than unrestricted prose.
Abstention
Define conditions under which the AI must not produce a directional conclusion: stale feeds, missing features, conflicting tools, unsupported instrument or out-of-distribution state. Measure abstention quality alongside prediction quality.
Prompt and Model Versioning
Prompts are production logic. Store their versions with model identifier, tool schema and evaluation results. A model upgrade can change behavior even when the visible prompt stays the same, so regression tests should accompany upgrades.
Evaluation Sets
Maintain representative cases for normal sessions, unusual volatility, missing data, contradictory context and known historical failures. Evaluate factual grounding, tool selection, numerical correctness and whether the system appropriately refuses unsupported conclusions.
Human Overrides
Record when users accept, reject or modify AI suggestions and why. Overrides can reveal weak model areas, but they are not automatically ground truth because humans also make mistakes. Treat them as evidence to review.
AI Security
Tool-using models face prompt injection and permission risks. Keep untrusted content separate from system instructions, validate destinations, use least privilege and require deterministic authorization for consequential actions.
Latency and Cost
A model that is excellent but too slow for the decision horizon is not operationally useful. Measure end-to-end latency, timeout behavior and cost per analysis. Use smaller deterministic components where they solve the task reliably.
AI in Review
Post-trade analysis is a lower-risk place for generative AI: summarize recurring rule violations, retrieve similar cases and propose research questions. Preserve source records and require the user to distinguish observations from generated hypotheses.
Regulatory and Claims Discipline
Avoid implying that AI removes risk or guarantees returns. Describe exactly what a model does and how it was evaluated. Extraordinary performance claims require extraordinary evidence and appropriate disclosures.
Related Guides
Read Machine Learning in Financial Markets for model-validation mechanics and Future of AI-Assisted Trading for governance-oriented scenarios.
Ground Truth
AI evaluation needs a defensible reference. For factual tasks, ground truth can come from authoritative structured data. For subjective market classifications, use explicit labeling rules and disagreement handling. A model cannot be meaningfully scored against labels whose definition changes from reviewer to reviewer.
Confidence Language
Separate model score from user-facing confidence. If a classifier is uncalibrated, do not translate 0.82 into '82% chance.' Language should reflect what the metric actually means and expose uncertainty when evidence is incomplete.
Counterfactual Evaluation
If AI changes a workflow, measure what would have happened without it where feasible. This is especially important for filters and recommendations: only looking at actions the AI allowed creates selection bias.
Model Failure Modes
Maintain a taxonomy: stale context, wrong retrieval, arithmetic error, unsupported inference, tool failure, format violation and overconfidence. Different failure types need different fixes; retraining is not the answer to every incident.
Change Management
A new prompt, tool schema, retrieval source or model can change production behavior. Treat each as a versioned release with regression tests and rollback. AI operations should borrow mature practices from software engineering.
Useful Success Criteria
Success may mean fewer unsupported analyses, faster journal review, better retrieval accuracy or improved rule adherence—not necessarily higher trading returns. Choose a metric that matches the AI's actual job.
Separate Generative Tasks From Deterministic Tasks
AI is strongest when the task tolerates interpretation: summarizing a research note, clustering journal comments, explaining a metric, comparing scenarios or retrieving relevant documentation. Exact calculations, risk limits, order quantities and position state should generally remain deterministic and independently verifiable.
This separation reduces the blast radius of hallucination. A model can propose an interpretation while software computes the actual tick value, risk or position from authoritative data.
The Position Sizing Guide is an example of deterministic arithmetic, while Trading Automation Explained shows why order and position state need explicit reconciliation.
Grounding Is More Than Adding Search
A grounded system should preserve which source supported which claim, when the source was retrieved, and whether the data is still current. Retrieval can fail too: the wrong document, stale page or irrelevant chunk can produce a confident but unsupported answer.
NIST's AI RMF frames risk management across governance, mapping, measurement and management, and its Generative AI Profile adds guidance specific to generative systems. Those concepts map well to trading-support tools: define the use case, test representative failures, monitor production behavior and keep rollback available.
Evaluate the Task You Actually Care About
Do not evaluate an AI assistant only on whether its prose sounds good. Build a test set with known answers, ambiguous cases, stale-data traps, missing-context cases and situations where abstention is the correct response. Score source fidelity, factuality, completeness and whether the model stayed inside its permitted role.
The Future of AI-Assisted Trading guide expands this into agents, permissions and long-term architecture; the Machine Learning guide covers predictive models and temporal validation separately.
Confidence Language Should Be Calibrated
A model should distinguish observed facts, calculations, hypotheses and uncertainty. “The data shows X” requires actual data; “one interpretation is X” communicates a different epistemic status. This matters in markets because fluent language can make weak evidence feel stronger than it is.
Investor.gov explicitly warns against relying solely on AI-generated information for investment decisions because outputs can be inaccurate, incomplete, misleading or fabricated. Its AI and Investment Fraud alert also warns about guaranteed-return claims associated with AI.
Human Control Is a System Property
Human-in-the-loop should mean more than placing an approval button at the end. Users need enough provenance to understand what the system used, clear boundaries on what it can change, and an independent way to verify consequential outputs. The Trading Journal Guide can preserve AI-assisted decisions for later review rather than allowing model output to disappear after the session.
AI can make a trading workflow more efficient and inspectable. It does not turn uncertain markets into a solved prediction problem.
Frequently Asked Questions
Can AI predict markets?
AI can model relationships and produce forecasts or classifications, but markets remain uncertain and predictions can fail. A model output is evidence, not certainty.
Where is AI most useful in a trading workflow?
Useful roles include information compression, classification, anomaly detection, retrieval, journal review and bounded analysis of structured market context.
How can hallucinations be reduced?
Ground the model in authoritative data, preserve timestamps and provenance, validate structured outputs, expose missing inputs and allow the system to abstain when evidence is stale or incomplete.
Should an AI model control trading risk by itself?
No. Position limits, order permissions, quantity calculations, reconciliation and kill switches should be deterministic and independently verifiable.
Final Takeaway
The most useful role for AI in trading is not pretending that uncertainty has disappeared. Build a grounded evidence chain with fresh data, provenance, calibrated language, deterministic controls and clear conditions for abstention or human review.